Abstract
Consumer devices now ship with generative image editing tools that can remove objects, move subjects, and create new visual content directly on phones, tablets, and laptops. Yet current benchmarks largely miss this setting: real on-device edits produced by black-box consumer generative AI editing tools, with variation across platforms, devices, edit operations, and post-edit compression. We introduce ConsumerGenEdit, a large-scale multilingual benchmark for language-guided localization of on-device generative image edits. The dataset contains 4,000 royalty-free source images and 48,000 manually edited images created on Apple, Google, and Samsung devices, covering object removal, object movement, and sketch-based object generation. To study robustness under realistic sharing conditions, we add 144,000 learned-compression variants at three quality levels. Each example includes platform, device, editing operation, compression metadata, bounding-box annotations, and edit descriptions in English, Bangla, and Persian/Farsi generated with five vision-language models (VLMs). We evaluate five separate benchmark VLMs on edit detection and edit-operation classification. By focusing on where and how consumer AI edits occur, rather than only whether an image is synthetic, ConsumerGenEdit provides a practical testbed for multilingual VLM grounding, image provenance, and robust interpretation of AI-edited media.
The ConsumerGenEdit Benchmark
Real devices, native tools
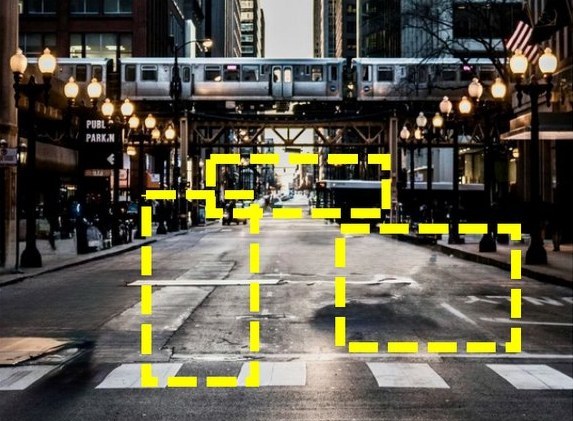
Apple Intelligence on iPhone, iPad and MacBook; Galaxy AI on the S25 Ultra; Magic Editor on Pixel. Seven standalone endpoints and five cross-device chains, where an image edited on one platform is edited again on another. Three operations: removal, movement and sketch-to-image.
Realistic sharing conditions
Every edit is recompressed with the Cheng 2020 learned codec, a precursor to JPEG AI, at three quality levels from about 0.83 down to 0.19 bits per pixel: a controlled stand-in for what upload, messaging and cloud sync do to an image.
Edit-aware multilingual captions
Five VLMs from 7B to 32B parameters see the original and the edited image together and describe the change in English, Bangla and Farsi, with an edit-type label and a confidence. 1,500 pairs carry independent human references.
Key Findings
| Model | Object (En) | Operation (En) | Full (En) | Full (Bn) | Full (Fa) |
|---|---|---|---|---|---|
| Gemma 3 27B | 62.8 | 55.8 | 35.8 | 14.7 | 21.8 |
| Qwen3-VL 32B | 77.9 | 42.3 | 32.7 | 39.3 | 35.9 |
| LLaVA-OV 7B | 55.6 | 49.9 | 28.0 | 0.4 | 1.6 |
| Pixtral 12B | 44.2 | 57.3 | 27.8 | 7.1 | 12.5 |
| Phi-4-RV 15B | 67.1 | 34.6 | 23.3 | 13.5 | 17.5 |
| Majority class | – | 62.2 | – | – | – |
| Human ceiling | – | – | 39.6 | 37.2 | 36.0 |
Accuracy (%) against human references on 1,500 pairs. Orange: below the majority-class baseline for the edit operation.
Five VLMs converge on a majority edit label, yet against human references none names the edit operation better than always predicting the most common class. Qwen3-VL is more often fully correct in Bangla and Farsi than any model is in English.
Paper §5.1–5.2Caption similarity, CLIP drift and CIDEr from Q2 to Q6 in each language (left); agreement of Bangla and Farsi captions with English, by model (right).
As quality drops, caption similarity and CIDEr fall in every language while CLIP drift stays near zero: captions lose specifics and models abstain more, but visual grounding holds and hallucination stays flat.
Paper §5.1BERTScore change and CLIP drift for each of the twelve editing endpoints (rows) by model, compression level and language (columns).
Read by column, not by row: both metrics move toward zero from Q2 to Q6 for every model and language, while the twelve endpoints, including cross-device chains, stay nearly flat.
Paper §5.1Top: balanced accuracy of five lightweight VLMs, zero-shot and few-shot, with the original image (pair) and without it (rf), against chance (0.50) and a GPT-4o reference (0.62). Bottom: detection rate by edit type.
Without a reference image, lightweight VLMs detect edits at chance; with it, only Qwen2.5-VL (0.69) and Phi-3.5-V (0.61) pull clear. Few-shot examples do not help. Removal remains the hardest edit to see.
Paper §5.3Full results, including the multilingual caption analysis, per-platform heatmaps, human-reference accuracy, NLI error analysis and detection ablations, are in the paper. Code is on GitHub; the data is on the dataset page.